Cohere Releases Embed 5: How It Compares to Voyage 4 Large, Gemini Embedding 2, and OpenAI
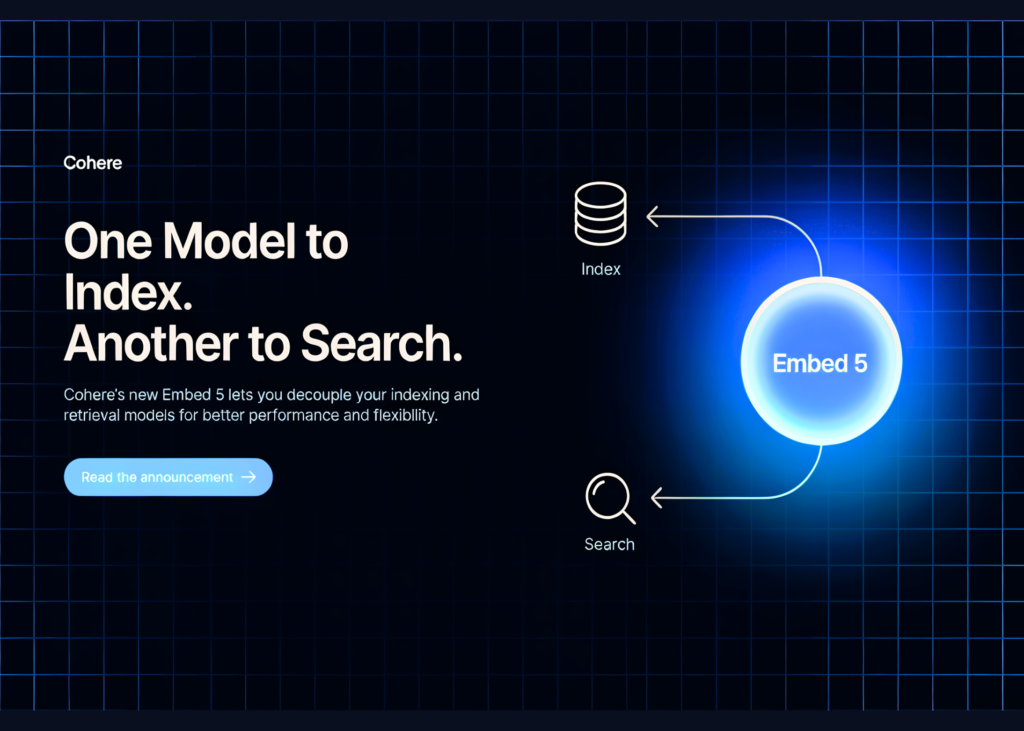
Cohere has released Embed 5, a new embedding model family. It targets enterprise search, RAG, and agentic retrieval. The model family ships in 2 tiers. Embed 5 Pro targets maximum retrieval quality. Embed 5 Fast targets latency and cost on the live query path. Both accept text, images, and fused text plus image inputs. Both cover 100+ languages and read up to 128K tokens. The key design choice: Pro and Fast share 1 embedding space. You can index with one and query with the other.
Is it deployable today? Yes, both tiers are generally available on the Cohere API and Model Vault, Microsoft Foundry, and Amazon SageMaker. Private VPC or on-prem serving runs through vLLM.
What Cohere Shipped
The API model IDs are embed-v5.0-pro and embed-v5.0-fast, per Cohere’s model docs. Both output 2048, 1536, 1024, 768, 512, or 256 dimensions, with 2048 as default. Embeddings come back as float, int8, or binary. Pro costs $0.12 per 1M text tokens. Fast costs $0.08. Image inputs cost $0.40 per 1M tokens on both.
Embed 5 can embed a page image directly. It can also fuse an image with its metadata into a single vector. That is important for scanned pages, slide decks, schematics, and charts, where text extraction drops information.
Pro and Fast: One Index, Two Query Paths
Cohere tested every corpus and query pairing across 40 development datasets. Normalized to Pro plus Pro at 100, a Pro index queried with Fast scored 98.4. An all-Fast setup scored 96.6. Cohere’s recommended pattern is to index with Pro and query with Fast. One constraint: both sides must use the same output dimension.
The split targets agentic workloads. An agent may issue dozens of searches per task, and query latency compounds. Cohere team reports Fast processed 377.3 documents per second versus 159.7 for Pro.
Benchmarks
On ViDoRe V3, Embed 5 Pro averages 85.8, an 8.8-point gain over Embed 4. Fast averages 84.5. Voyage 4 Large scores 83.7, Gemini Embedding 2 scores 83.2, and OpenAI text-embedding-3-large scores 75.5. On Cohere’s parsed-PDF suite, Pro leads at 84.8 against Voyage 4 Large at 83.6.
Finance is the strongest showing. Pro ranks first on FinanceBench (80.1), FinQA (90.0), and ViDoRe V3 Finance (85.0). Fast ranks second on all 3.
Multilingual results are mixed. Pro leads the European-language average at 77. However, Gemini Embedding 2 beats Pro on 9 of 10 further languages in Cohere’s own results table. Those include Japanese, Arabic, Hindi, and Telugu.
One important thing to note. Most numbers use RCP-nDCG@10, a new Cohere metric. It reorders a fixed candidate set, so it measures reranking quality more than first-stage retrieval. Cohere published the evaluation code, but independent replication is still pending.
Storage Costs at Scale
Embed 5 uses Matryoshka representation learning plus lower-precision outputs. A 2048-dim float32 vector needs 8 KB. A 1024-dim int8 vector needs 1 KB. A 256-dim binary vector needs 32 bytes. Across 100M chunks, raw storage drops from about 819 GB to 3.2 GB. Cohere recommends 1024-dim int8 as the default, citing near-full-precision quality.
Interactive Explainer: How Embed 5 Works
Cohere Embed 5 Explainer | Marktechpost
Cohere Embed 5 · Interactive explainer1 / 6
1. What an embedding model actually does
Text goes in, a vector of numbers comes out. Search then ranks documents by how close their vectors sit to the query vector. Press the button to watch it run.
Query
What happened to net interest margin last quarter?
Embed and searchModel: embed-v5.0-pro · 1024 dims
Documents ranked by cosine similarity
Net interest margin narrowed 12 bps to 2.61% as deposit costs rose.0.00
Torque the mounting bolts to 45 Nm in a star pattern before refitting the cover.0.00
Employees accrue 1.5 days of paid leave for each month of service.0.00
Documents come from Cohere’s launch code sample. Vector bars and similarity scores here are illustrative, not real model output.
2. Two tiers, one embedding space
Pro and Fast write vectors into the same space. Pick which model indexes the corpus and which one embeds the query. Quality is normalized so Pro plus Pro equals 100.
Index corpus with
ProFast
Embed queries with
ProFast
Cohere’s recommended pattern: index with Pro, query with Fast.
Ring zoomed to the 90 to 100 range so small gaps are visible.
Document throughput (docs per second, Cohere-measured)
Price per 1M text tokens: Pro $0.12, Fast $0.08. Images cost $0.40 per 1M tokens on both tiers.
3. Shrink the vector, not the quality
Matryoshka training lets you truncate dimensions. Lower precision outputs cut bytes further. Change the settings and watch storage move.
Output dimensions
204815361024768512256
Precision
float32int8binary
Chunks in your index: 100,000,000
8,192 Bbytes per vector
819.2 GBraw vector storage
1xsmaller than 2048 float32
Storage vs 2048-dim float32 baseline100%
Math: dims x bytes per value (4, 1, or 1/8). Cohere recommends 1024-dim int8 as the default sweet spot. Binary trades some accuracy and suits a first pass before reranking.
4. How it scores against rivals
Cohere-reported averages using its new RCP-nDCG@10 metric. Treat these as vendor numbers until independent runs land.
ViDoRe V3Parsed PDFsFinance
Source: Cohere Embed 5 launch post, Sep 30 2026. RCP-nDCG@10 reorders a fixed candidate set, so it reflects reranking quality more than first-stage recall.
5. How much fits in one input
A longer context means fewer chunks for long filings and manuals. Press play to compare maximum input length per call.
Cohere Embed 5 Pro / Fast128K tokens
Voyage 4 Large32,000 tokens
Gemini Embedding 28,192 tokens
OpenAI text-embedding-3-large8,191 tokens
Limits taken from each vendor’s model docs. 128K is shown as 131,072 tokens for bar scale.
6. Is it deployable? Yes. Pick a route.
Both tiers are generally available. Tap a route to see what it gives you.
Cohere APIManaged endpoint
Model VaultDedicated inference
Microsoft FoundryAzure catalog
Amazon SageMakerAWS Marketplace
Private VPC / on-premServed with vLLM
Cohere NorthBuilt-in retrieval
Embed 5 vs Closest Competitors
Sources: Cohere blog, Cohere docs, Voyage docs, Google Gemini docs, OpenAI docs. Verified October 1, 2026. Benchmark scores come from Cohere and use its RCP-nDCG@10 metric.
FAQ
What is Cohere Embed 5? A multimodal, multilingual embedding model family from Cohere, released September 30, 2026, in Pro and Fast tiers.
How much does Embed 5 cost? Pro costs $0.12 and Fast costs $0.08 per 1M text tokens. Images cost $0.40 per 1M tokens on both.
Can I mix Pro and Fast embeddings? Yes. They share 1 embedding space, provided both use the same output dimension.
Check out the technical details, product page, and announcement on X. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Sana Hassan, a consulting intern at Marktechpost and dual-degree student at IIT Madras, is passionate about applying technology and AI to address real-world challenges. With a keen interest in solving practical problems, he brings a fresh perspective to the intersection of AI and real-life solutions.
Originally published by marktechpost.com →