Meta Releases Muse Ember, a 1M-Context Model for High-Volume Agent Work
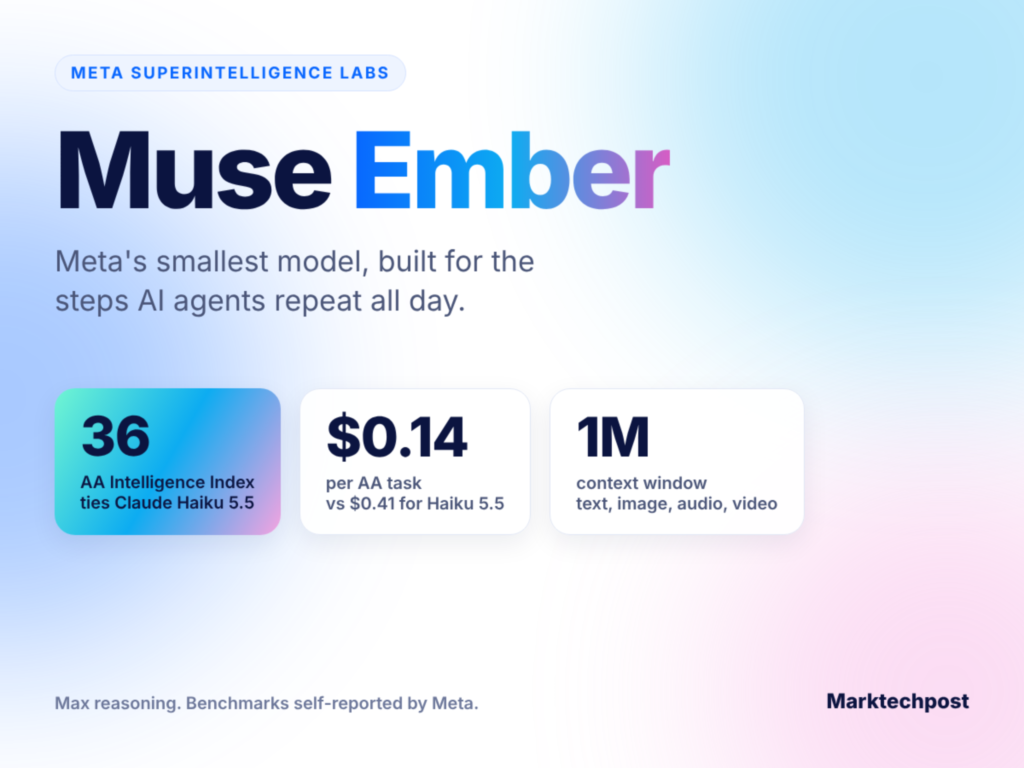
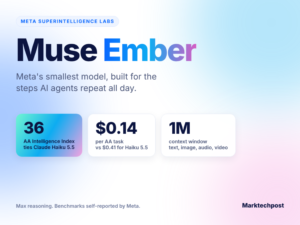
Meta Superintelligence Labs has released Muse Ember, its smallest and most efficient model. Meta Muse Ember is a hosted multimodal reasoning model built for the repetitive steps inside agents. Meta lists tool calls, coding subtasks, routing, extraction and long document parsing as targets. It scores 36 on the Artificial Analysis Intelligence Index, level with Claude Haiku 5.5 at max effort. Meta puts its cost at about $0.14 per index task.
Muse Ember is a small reasoning model from Meta for high-volume agent subtasks. It is the fourth model under the Muse brand, after Spark, Glimmer and Wonder.
Meta positions it below its larger models. Muse Wonder handles the hardest problems and Muse Spark covers coding and agentic workflows. Ember takes repeatable coding and agent tasks at scale. Meta’s own framing: Muse Wonder plans, Muse Ember handles the volume.
How does Muse Ember work?
Muse Ember is the first model Meta trained using Muse Wonder Full, its largest model.
The model natively accepts text, images, audio and video. That lets an agent read screenshots, charts, scanned pages, voice memos and meeting recordings without a separate model. It also operates desktop apps from screenshots.
The 1M-token context window fits a full codebase or document set in one call. Output runs up to 512K tokens, 4x the 128K cap on both rivals.
How does Muse Ember perform on benchmarks?
All results below are at max reasoning effort, as reported by Meta. Some come from Artificial Analysis (AA), others from Meta’s internal suite.
Agents: On AutomationBench-AA, 657 Zapier business workflows, Ember completes 37.8% of tasks. GPT-6 Luna reaches 20.2% and Claude Haiku 5.5 reaches 13.9%. On Agents’ Last Exam (internal), Ember scores 61.6 versus 57.1 and 57.0.
Coding: Ember leads Terminal-Bench 4.0 with 40.9 versus Haiku’s 39.2 and Luna’s 16.4. It also leads the AA Coding Agent Index, 46 to 37 to 31. It loses FrontierCode 2.0-AA, where Haiku scores 34.9 and Ember 27.2.
Multimodal: Ember ties GPT-6 Luna on GDP.pdf-AA at 22.8. It edges Haiku on OSWorld 2.1, 69.5 versus 68.9 on partial credit. PerceptionBench with tools gives Ember 80.6, Haiku 78.6 and Luna 62.8.
Why is Muse Ember cheaper per task if token prices match?
Muse Ember costs $0.10 per million input tokens and $0.50 per million output tokens. Cached input costs $0.004 per million. Claude Haiku 5.5 and GPT-6 Luna list the same base rates.
With identical list prices, the cost gap must come from tokens used per task. On Meta’s chart, Ember at max scores 35.8 for $0.136 per task. Haiku 5.5 at max scores 36.2 for $0.411. Luna’s best setting scores 27.8 for $0.152. Artificial Analysis summarised this as matching Haiku at a third of the cost per task.
Long prompts widen the gap on paper. Haiku 5.5 charges $0.50 and $2.50 above 100K prompt tokens. GPT-6 Luna doubles input rates above 272K input tokens. Meta lists no long-context tier for Ember.
Muse Ember vs Claude Haiku 5.5 vs GPT-6 Luna
*Benchmark rows as published by Meta in its launch post and evaluation report, sourced from Artificial Analysis Intelligence Index v5 and Meta internal runs.
How can developers access Muse Ember?
Ember is available on the Meta Model API and in Muse Code, Meta’s coding agent. It supports the Responses API. Partners in early testing included Box, Cline, Oracle, Cloudflare and You.com.
Check out the launch post and the evaluation report, or try it on dev.meta.ai.. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
Originally published by marktechpost.com →