Samaya AI Releases Sterling: A 3B-Active Finance Research Agent Model that Beats Claude Fable 5.1 on FrontierFinance at 11x Lower Cost
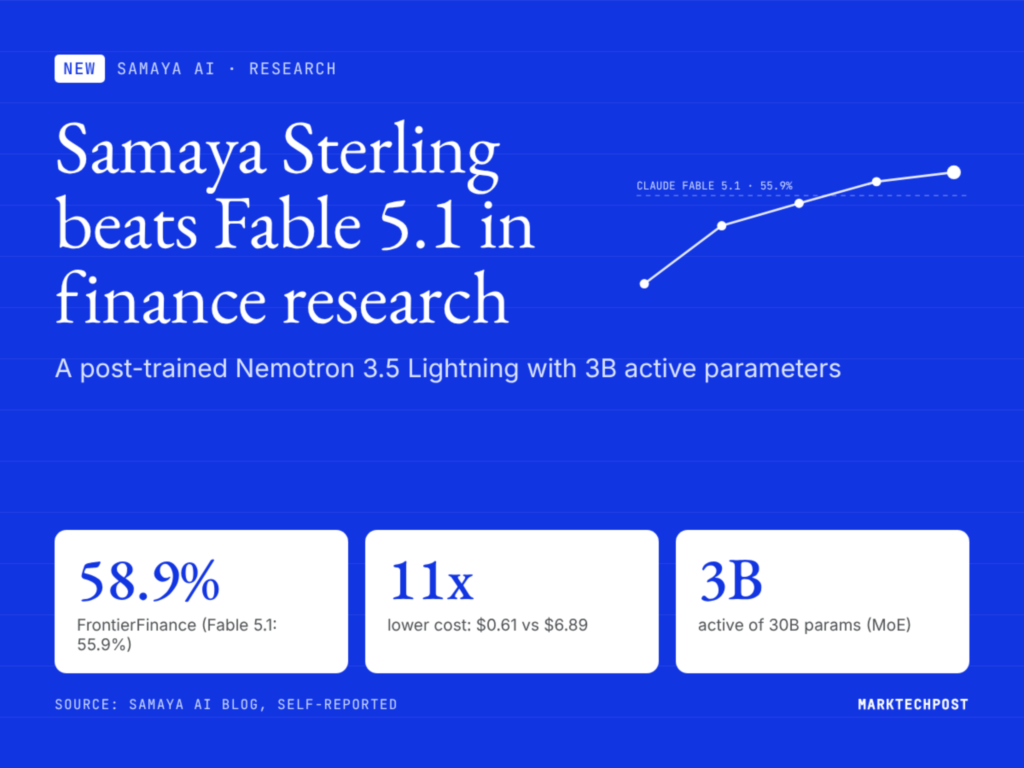
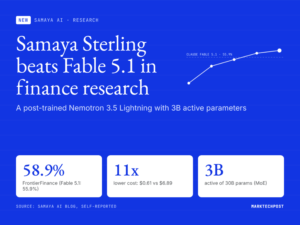
Samaya AI has released Samaya Sterling, a post-trained model for agentic financial research. Sterling is built on NVIDIA’s Nemotron 3.5 Lightning, a 30B mixture-of-experts model with 3B active parameters. On Samaya’s FrontierFinance benchmark, it scores 58.9%. Claude Fable 5.1 scores 55.9%. Each Sterling question costs $0.61, against $6.89 for Fable 5.1. For developers, the takeaway is a concrete recipe: co-train a small model with its harness, and it can win in a narrow domain.
What is Samaya Sterling?
Samaya Sterling is a LoRA post-trained version of Nemotron 3.5 Lightning, tuned to work as a financial research agent. It plans research, calls finance tools, gathers evidence and hands findings to a separate report writer. According to Maithra Raghu’s X announcement, it started as a 2-person effort on agentic orchestration efficiency.
How does the harness support a 3B-active model?
Samaya team adapted its production finance harness for a small model. Detailed guidance was stripped from the system prompt and tool descriptions. Tools were merged to shorten the prompt. Two helper models manage context. A condenser shortens long tool results. A compactor summarizes the trace as it grows. A research budget caps how long the agent works. After that, the report writer answers from what was found.
How was Sterling trained?
Training used LoRA on Tinker, Thinking Machines Lab’s training API. It ran in 4 stages:
SFT on synthetic traces: Samaya generated 968 synthetic analyst questions. The teacher, Kimi K3, answered each twice, and an LLM judge picked the better answer. The model learned to call 37 tools with valid arguments.
SFT on the best of 8 strategies: Kimi K3 answered 1,819 expert-written questions using 8 research strategies. The best-graded answer per question became training data. Best-of-8 met 80% of essential rubric items, against about 66% for the single best strategy. After filtering, 1,157 questions remained.
Offline GRPO: GRPO scored all 8 teacher answers against each other. No new generation was needed, so each step was cheap.
Online GRPO: The model answered each question 8 times and learned from graded attempts. Truncated importance sampling corrected a known MoE sampler mismatch.
How does Sterling score on FrontierFinance?
FrontierFinance has 220 public queries scored against expert-written rubrics. The grader uses a 3-model judge panel. Samaya team states that no benchmark question was used in training. Checkpoints were chosen on 100 internal validation questions.
Sterling scores 58.9% at $0.61 and 282 s per question. Fable 5.1 scores 55.9% at $6.89 and 268 s. Samaya’s own high-effort system scores 2.9 points lower at $1.81.
Every stage added quality: 42.5% (base), 51.4%, 54.8%, 57.5%, then 58.9%. Median tool calls rose from 3 to 17. In high-effort mode, Sterling reaches 60.6% at $1.83 and 372 s. On the hardest third, it rose from 31.8% to 45.2%.
The model itself costs $0.04 per question. Tools and helper models make up the rest of the $0.61.
How does Sterling compare?
FrontierFinance figures for all columns come from the Samaya blog and are self-reported.
Check out the technical blog, the FrontierFinance benchmark, the dataset and the grader repo. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
Originally published by marktechpost.com →