JetBrains Releases Mellum2.1: A 12B MoE Open Model for Coding Agents
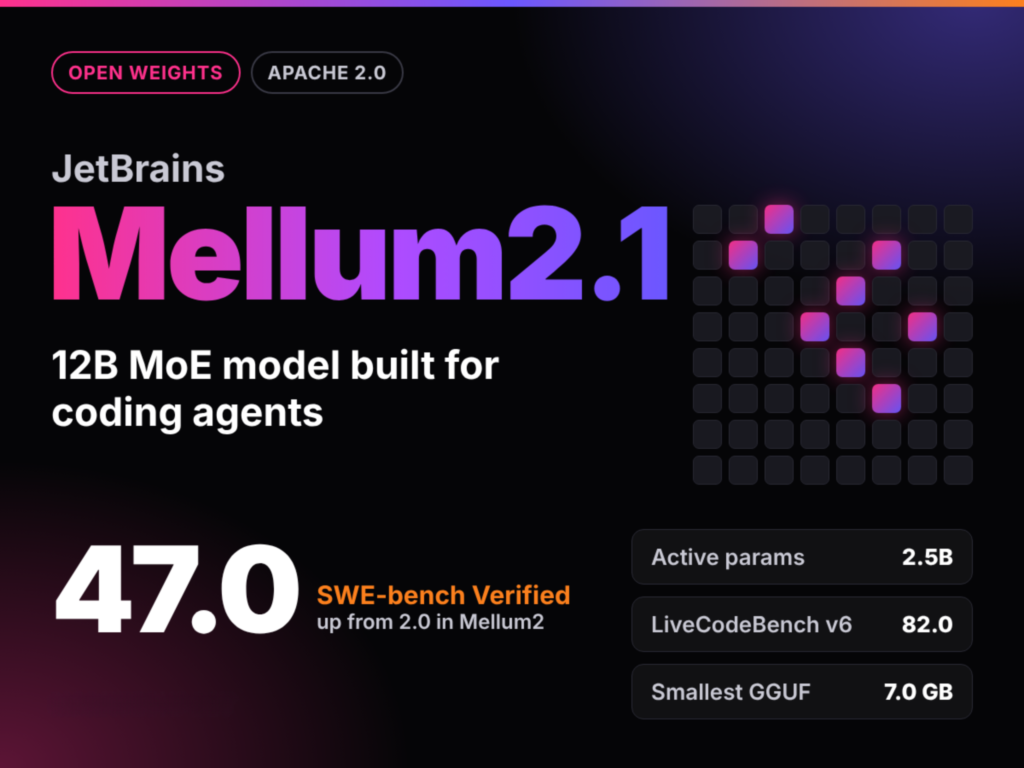
JetBrains has released Mellum2.1, an open model built for coding agents and fast sub-agents. Mellum2.1 is a 12B mixture-of-experts thinking model from JetBrains that activates 2.5B parameters per token. It ships under Apache 2.0 on Hugging Face. The architecture is unchanged from Mellum2. The upgrade comes almost entirely from reinforcement learning (RL) in real software environments. The result is a small, self-hostable model that explores a repository, edits files, and checks its own changes.
What is Mellum2.1?
Mellum2.1 is the next version of Mellum2 Thinking, which JetBrains open-sourced in June 2026. The released checkpoint is Mellum2.1-12B-A2.5B-Thinking. It is a reasoning model that emits its chain of thought before answering. JetBrains targets 3 uses: agent worker, general reasoning assistant, and private self-hosted deployment.
How does the Mellum2.1 architecture work?
The model has 28 layers and 64 experts. A router activates 8 experts per token. Attention uses grouped-query attention with 32 query heads and 4 KV heads. 3 of every 4 layers use a 1,024-token sliding window. Context length is 131,072 tokens, and the vocabulary has 98,304 tokens. Weights ship in bfloat16.
How was Mellum2.1 trained?
Almost all of the new work went into post-training. RL moved from a short final stage to the main part of training. JetBrains added RL tasks in math, competitive programming, science, tool use, and software engineering. It filtered open RL datasets for broken tests, unverifiable answers, and tasks that were too easy or impossible. For software engineering, the model trains in real repositories with a shell and file-editing tools. It is rewarded when the tests pass. Training launched millions of sandboxes across thousands of environments.
How does Mellum2.1 perform on benchmarks?
JetBrains evaluated Mellum2.1, Mellum2, Qwen3.5-9B and Gemma 4 E4B with one pipeline in thinking mode. All scores are self-reported by JetBrains.
The largest jump is agentic coding. SWE-bench Verified rose from 2.0 to 47.0. SWE-bench Pro rose from 0.0 to 28.0. Terminal-Bench 2.1 rose from 0.6 to 17.4. Agentic runs used the open-source Pi v0.73.1 harness with a 114K-token context.
Mellum2.1 leads the group on LiveCodeBench v6 (82.0), HumanEval+ (91.5), MBPP+ (79.4) and BFCL v4 (62.3). Qwen3.5-9B still leads on SWE-bench Verified (50.0), SWE-bench Pro (38.0), AIME 25/26 (86.7) and GPQA Diamond (77.8). Safety also improved: HarmBench fell from 21.5 to 8.5, where lower is better.
Pipelines are important to consider. Qwen’s own card lists 65.6 on LiveCodeBench v6 and 81.7 on GPQA Diamond. JetBrains measured 75.4 and 77.8 for the same model.
How fast is Mellum2.1?
Post-training left the architecture untouched, so speed matches Mellum2. On 1 H200 under heavy load, JetBrains says Mellum2.1 serves almost 2x the tokens of Qwen3.5-9B. For a single request, multi-token prediction (MTP) makes it about 1.6x faster. The MTP head for vLLM speculative decoding is listed as coming soon.
How do you run Mellum2.1 locally?
The full model serves on vLLM with –reasoning-parser qwen3. Tool calling adds –enable-auto-tool-choice –tool-call-parser hermes. JetBrains recommends temperature 0.6, top_p 0.95 and top_k 20.
The JetBrains release notes mentions that GGUF builds are in progress. A GGUF repository already lists 5 files:
BF16: 24.3 GB (reference)
Q8_0: 12.9 GB, 96.1% top-token match
Q6_K: 10.9 GB, 93.9% top-token match
Q4_K_M: 8.1 GB, 88.0% top-token match (recommended)
MXFP4_MOE: 7.0 GB, 85.6% top-token match
Mellum2.1 vs Qwen3.5-9B vs Gemma 4 E4B
*Benchmark rows: JetBrains’ shared pipeline, thinking mode, from the Mellum2.1 model card. Vendors’ own cards report different numbers for Qwen3.5-9B and Gemma 4 E4B.
Check out the model weights, GGUF builds, technical blog and the Mellum2 technical report. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
Originally published by marktechpost.com →